Ideas used to stay as ideas until someone had the time, equipment, budget, and production resources to turn them into video.
That is changing.
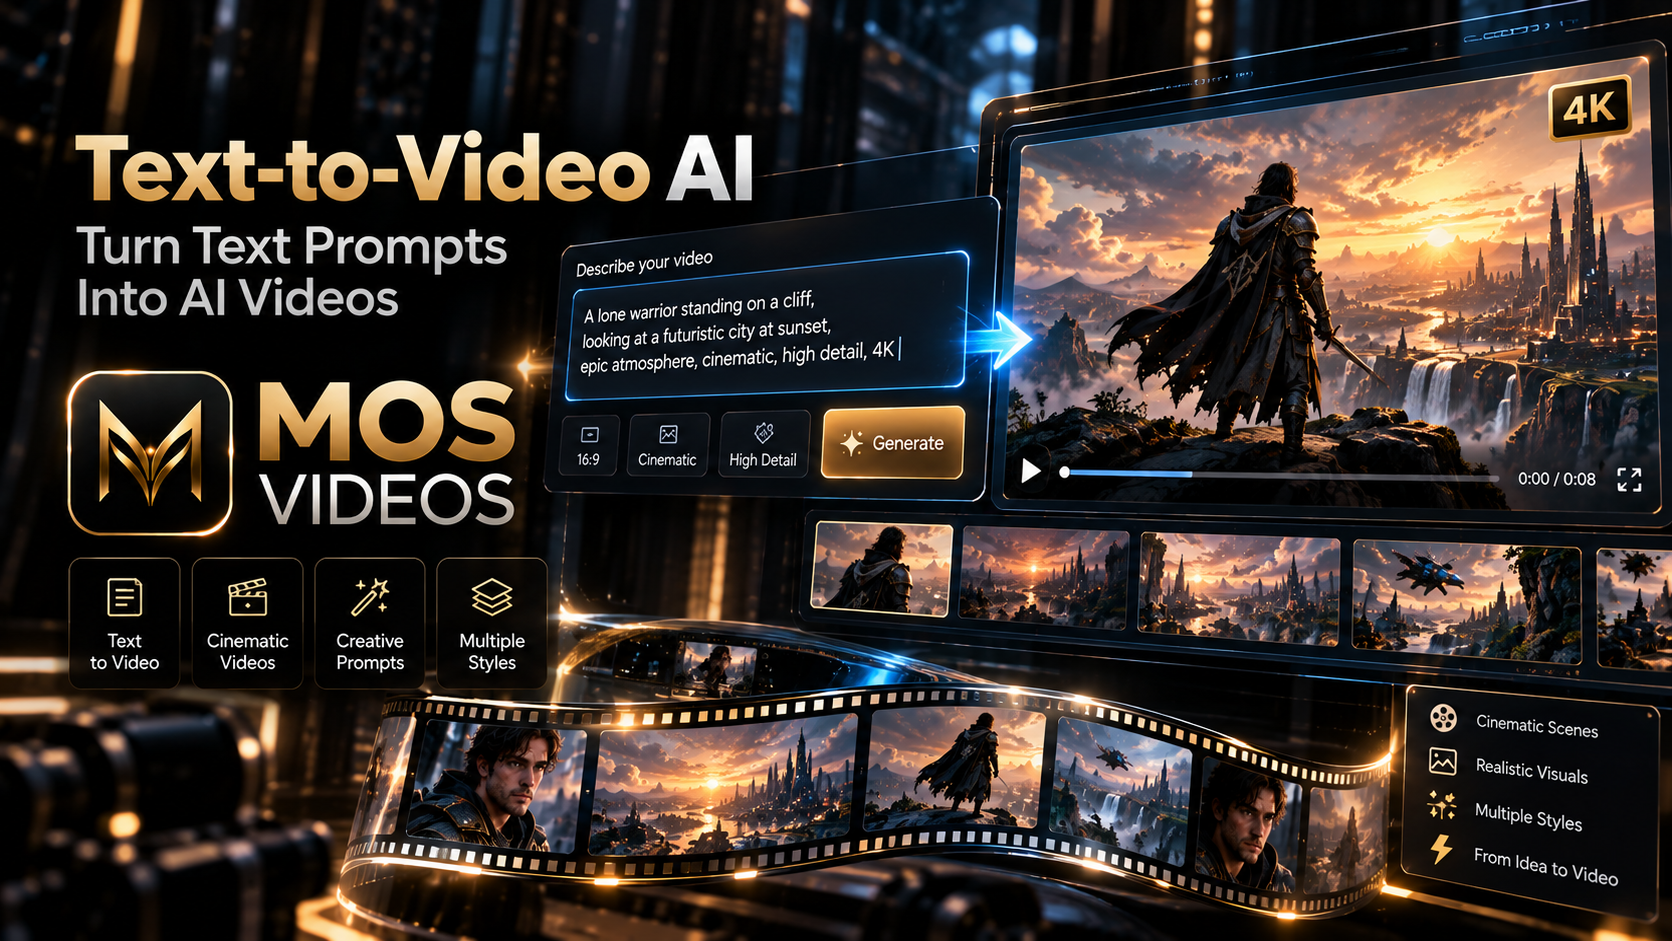
Text-to-Video AI allows creators to transform written prompts into moving visual content using artificial intelligence.
A sentence can become a scene.
A concept can become a cinematic sequence.
A written description can become video.
With MOS Videos, creators can use text as the starting point for AI-powered video generation and build visual content from simple creative instructions.
Instead of asking:
“How do I film this?”
Creators can begin with:
“How do I describe this?”
That shift is what makes Text-to-Video AI so powerful.
What Is Text-to-Video AI?
Text-to-Video AI is a generative artificial intelligence technology that creates video content from written prompts.
Users describe the scene they want to create, and the AI generates moving visual content based on that description.
A prompt may include:
- Subject
- Action
- Environment
- Camera movement
- Lighting
- Mood
- Style
- Visual composition
For example:
A futuristic motorcycle moving through a neon city at night, cinematic tracking shot, wet streets, realistic reflections, dramatic lighting.
The AI interprets those instructions and turns them into video.
How Does Text-to-Video AI Work?
Text-to-Video AI combines language understanding with generative video technology.
A simplified workflow looks like this:
Text Prompt
↓
AI Interpretation
↓
Scene Generation
↓
Motion Creation
↓
Video Output
The AI analyzes the meaning of the prompt and identifies visual concepts.
Then it generates frames that attempt to represent:
- What is in the scene
- What is moving
- How the camera behaves
- What the lighting looks like
- What visual style should be used
This allows written language to become part of the video production process.
Turn a Simple Prompt Into Video
A very simple prompt might be:
A car driving at night.
That can work, but it gives the AI very little direction.
A stronger prompt could be:
A black futuristic sports car driving through a neon-lit city at night, low-angle cinematic tracking shot, wet streets reflecting lights, realistic motion, dramatic atmosphere.
The second prompt gives the AI much more context.
It explains:
- The subject
- The environment
- The time
- The camera
- The lighting
- The mood
- The style
This usually gives the creator more control over the result.
How to Write a Better Text-to-Video Prompt
A practical structure is:
Subject + Action + Environment + Camera + Lighting + Style
For example:
A futuristic explorer walking through an abandoned city, slow tracking shot, dust moving through the air, dramatic sunset lighting, photorealistic cinematic style.
This structure is simple enough to use quickly but detailed enough to communicate creative intent.
1. Define the Subject
Start by describing the main focus of the scene.
Examples:
- A futuristic soldier
- A sports car
- A robot
- A woman in a cyberpunk city
- A spacecraft
- A luxury product
The subject should be clear.
2. Add the Action
Video needs movement.
Describe what is happening.
Examples:
- Walking
- Running
- Flying
- Driving
- Turning toward the camera
- Moving through a city
- Opening a door
- Looking at the horizon
Action gives the scene energy.
3. Describe the Environment
Explain where the scene takes place.
Examples:
- Futuristic city
- Desert
- Luxury studio
- Alien planet
- Tropical beach
- Medieval castle
- Modern office
The environment helps define the visual world.
4. Add Camera Direction
Camera movement can change the entire feeling of the video.
Useful terms include:
- Tracking shot
- Dolly forward
- Slow zoom
- Drone shot
- Wide shot
- Close-up
- Orbiting camera
- Low-angle shot
For example:
Slow cinematic tracking shot following the subject.
This tells the AI how the scene should be visually presented.
5. Define the Lighting
Lighting can create atmosphere.
Examples:
- Cinematic lighting
- Golden hour
- Neon lighting
- Soft studio lighting
- Dramatic shadows
- Moonlight
- Volumetric light
For example:
Warm golden-hour lighting with long cinematic shadows.
This gives the scene a stronger visual direction.
6. Define the Style
The final prompt can also describe the visual style.
Examples:
- Photorealistic
- Cinematic
- Documentary
- Futuristic
- Fantasy
- Minimalist
- Surreal
- Luxury commercial
Style helps determine the overall look and feel.
Text-to-Video AI for Content Creators
Content creators can use Text-to-Video AI to generate visual scenes for:
- YouTube
- TikTok
- Instagram Reels
- Shorts
- Storytelling
- Faceless content
- Educational videos
- Creative projects
Instead of searching endlessly for footage that matches an idea, creators can generate visual content designed specifically for the script or concept.
Text-to-Video AI for YouTube
YouTube creators can integrate AI-generated video into many formats.
Examples include:
- Documentaries
- Technology channels
- Storytelling
- Educational videos
- Faceless channels
- AI filmmaking
- Visual essays
- Tutorials
Text-to-Video AI can be used to create scenes that support narration.
For example:
Script
↓
Scene Prompt
↓
AI Video
↓
Voiceover
↓
Final YouTube Video
This creates a more visual production workflow.
Text-to-Video AI for Social Media
Social media content needs to capture attention quickly.
AI-generated video can help create unusual or visually strong scenes.
Creators can generate:
- Cinematic clips
- Visual hooks
- Product scenes
- Fantasy concepts
- Futuristic environments
- Short narrative sequences
These videos can then become part of Reels, Shorts, and TikTok content.
Text-to-Video AI for Marketing
Marketing teams can also benefit from prompt-based video creation.
Potential use cases include:
- Advertising concepts
- Product campaigns
- Brand visuals
- Promotional videos
- Social ads
- Creative prototypes
A written idea can become a visual concept before larger production decisions are made.
This makes generative video useful not only for final content, but also for experimentation.
Text-to-Video AI for Storytelling
Storytelling is one of the strongest use cases for generative video.
A creator can write:
A lone traveler enters an abandoned futuristic city at sunrise.
That sentence can become the foundation for a visual scene.
A full story can be divided into multiple prompts.
For example:
Scene 1: Arrival
Scene 2: Discovery
Scene 3: Conflict
Scene 4: Resolution
Each scene can become a separate AI-generated video sequence.
This gives independent creators new ways to visualize narratives.
Text-to-Video AI for AI Filmmaking
Generative video can support modern filmmaking workflows.
AI can be used for:
- Concept scenes
- Previsualization
- Experimental shots
- Environment creation
- Visual storytelling
- Camera tests
- Scene development
The creative direction still comes from the creator.
The AI helps transform that direction into visual output.
Text-to-Video AI vs Traditional Video Production
Both methods have different strengths.
| Text-to-Video AI | Traditional Video Production |
|---|---|
| Starts with a prompt | Starts with filming |
| AI generates the scene | Camera captures real footage |
| Useful for impossible or fictional visuals | Best for real-world scenes |
| Fast concept testing | Precise physical production |
| Flexible visual experimentation | Greater manual control |
Creators can also combine both.
AI-generated scenes can be mixed with traditional footage.
Text-to-Video AI vs Image-to-Video AI
These workflows are related but different.
Text-to-Video AI starts from written instructions.
Image-to-Video AI starts from a visual reference.
Text-to-Video is useful when the creator wants the AI to design the initial visual scene.
Image-to-Video is useful when the creator already knows exactly how the scene should look.
A combined workflow can be:
Text Prompt
↓
AI Image
↓
Image-to-Video
This gives creators even more control.
Text-to-Video AI and Prompt Engineering
Prompt engineering is one of the most important skills in generative video.
Small changes in wording can affect the result.
Compare:
A man walking in a city.
with:
A man wearing a dark coat walking through a futuristic city during heavy rain, slow cinematic tracking shot, neon reflections, dramatic lighting, photorealistic style.
The second prompt communicates a much clearer creative direction.
Create Cinematic Videos from Text
Cinematic video generation often depends on combining several visual instructions.
A strong cinematic prompt can include:
- Subject
- Camera motion
- Lighting
- Atmosphere
- Environment
- Color direction
- Visual style
For example:
Slow aerial shot above a futuristic coastal city at sunset, flying vehicles between glass towers, golden cinematic lighting, atmospheric clouds, realistic motion.
This describes not only what happens, but how the scene should feel.
Create Product Videos from Text
Text-to-Video AI can also support product visualization.
For example:
A luxury black smartwatch rotating slowly in a dark premium studio, gold reflections, cinematic product lighting, high-end commercial style.
This can help brands experiment with visual concepts without requiring a physical shoot for every idea.
Create Advertising Concepts with AI
Advertising often begins with concepts.
Text-to-Video AI can turn those concepts into early visual prototypes.
A marketing team can test:
- Different environments
- Different products
- Different moods
- Different camera styles
- Different brand directions
This can accelerate creative exploration.
Text-to-Video AI for Faceless Content
Faceless creators often need visuals that support narration.
AI video generation can be especially useful for:
- Story channels
- Educational channels
- Documentary content
- Motivational videos
- Technology content
- Historical storytelling
The creator can generate specific scenes rather than relying only on generic stock footage.
From Script to AI Video
One useful workflow is:
Write the Script
↓
Divide the Script into Scenes
↓
Write a Prompt for Each Scene
↓
Generate AI Videos
↓
Add Voiceover
↓
Edit the Final Video
This turns a written script into a visual production plan.
Text-to-Video AI and AI Voice
Text-to-Video becomes even more powerful when combined with AI voice generation.
A creator can write a script.
Generate the narration.
Create visual scenes from the same script.
Then combine both.
The workflow becomes:
Script
↓
AI Voice
↓
Text-to-Video
↓
Editing
↓
Final Content
This is a strong example of multimodal AI creation.
Text-to-Video AI and AI Audio
Audio gives generated video more impact.
A complete production may include:
- Narration
- Music
- Sound effects
- Ambient audio
This means AI video creation does not need to stop at the visual layer.
It can become part of a complete multimedia workflow.
Text-to-Video AI and MOS Videos
MOS Videos is designed around connected generative workflows.
Text-to-Video AI can become the starting point for content that later includes:
- AI images
- AI voice
- AI audio
- Lip sync
- Talking avatars
- Translation
- Multilingual content
This allows creators to build more complete projects instead of generating isolated clips.
Create Videos from Prompts with MOS Videos
The process begins with a simple creative direction.
For example:
A futuristic athlete training alone inside a dark high-tech gym, dramatic cinematic lighting, slow tracking shot.
That idea can become a generated video.
From there, creators can continue developing the project with:
- Voice
- Audio
- Additional scenes
- Images
- Editing
- Localization
MOS Videos helps turn prompts into part of a broader creative process.
Why Use MOS Videos for Text-to-Video AI?
MOS Videos is designed for creators who want to move between different forms of generative media.
A project may begin as text but eventually require:
- Video
- Images
- Voice
- Audio
- Characters
- Translation
Instead of treating these as completely separate creative stages, MOS Videos supports a more connected workflow.
Create More Than One Scene
Text-to-Video AI becomes much more useful when creators think beyond a single generation.
A complete video may contain several AI-generated scenes.
For example:
Scene 1: Establishing shot
Scene 2: Character introduction
Scene 3: Main action
Scene 4: Close-up
Scene 5: Final cinematic shot
Each scene can use a separate prompt.
This creates a more structured and intentional production.
Text-to-Video AI and the Future of Content Creation
Natural language is becoming a creative interface.
Creators can increasingly describe what they want and work with artificial intelligence to generate visual media.
This changes the role of video creation.
The creator becomes more like a director.
They define:
- The idea
- The scene
- The mood
- The camera
- The story
- The final selection
The AI helps generate the raw visual material.
Turn Your Ideas Into Video with MOS Videos
Every video starts with an idea.
Text-to-Video AI shortens the distance between that idea and the visual result.
Write the prompt.
Define the scene.
Generate the video.
Refine the concept.
Build the final content.
With MOS Videos, text can become the beginning of a complete generative media workflow.
Describe the idea.
Generate the scene.
Create with MOS Videos.
Key Takeaways
- Text-to-Video AI turns written prompts into video content.
- Strong prompts define subject, action, environment, camera, lighting, and style.
- Text-to-Video AI can support YouTube, social media, marketing, storytelling, and filmmaking.
- Prompt engineering gives creators greater control over generated scenes.
- Text-to-Video can be combined with AI image, voice, and audio workflows.
- MOS Videos supports a broader creative ecosystem around AI-generated video.
Frequently Asked Questions
What is Text-to-Video AI?
Text-to-Video AI is generative artificial intelligence technology that creates moving visual content based on written prompts.
How does Text-to-Video AI work?
The AI analyzes a prompt, identifies visual concepts such as subjects, environments, movement, lighting, and style, and generates a video based on those instructions.
How do I create a video from text with AI?
Write a detailed prompt describing what should appear in the scene, what should happen, how the camera should move, and what visual style you want, then use a Text-to-Video AI generator to create the video.
What makes a good Text-to-Video prompt?
A useful prompt typically includes the subject, action, environment, camera movement, lighting, atmosphere, and visual style.
Can Text-to-Video AI create cinematic videos?
Yes. Prompts can include cinematic camera movements, lighting, composition, and visual style to guide the generation toward a more cinematic result.
Can Text-to-Video AI be used for YouTube?
Yes. It can support documentary content, storytelling, faceless channels, educational videos, technology content, and other YouTube formats.
What is the difference between Text-to-Video and Image-to-Video?
Text-to-Video begins from written instructions, while Image-to-Video begins from an existing image used as the visual reference.
How does MOS Videos fit into Text-to-Video AI?
MOS Videos supports generative workflows involving AI video, images, voice, audio, and other media, allowing Text-to-Video creation to become part of a broader multimedia production process.
